Author: admin

  • Red Chillies Entertainment, NOV Digital Entertainment, and Laughter Chefs – Unlimited Entertainment (2026)

    Red Chillies Entertainment, NOV Digital Entertainment, and Laughter Chefs – Unlimited Entertainment (2026)


    There is more entertainment than ever in 2026. People don’t only go to the cinema nowadays. They now watch videos, read articles, and listen to music on OTT platforms, YouTube, reels, and other digital media. That’s why terms like Red Chillies Entertainment, NOV Digital Entertainment, and Laughter Chefs – Unlimited Entertainment are becoming popular

    Red Chillies Entertainment is one of the most recognized production and VFX firms in India. It is known for making big movies with great visual effects. On the other hand, NOV Digital Entertainment is part of the developing digital entertainment business, where creators and digital platforms are becoming quite popular.

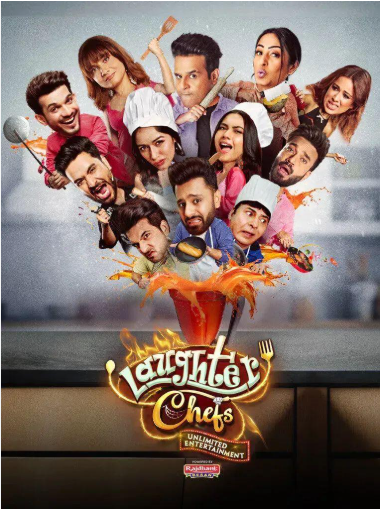
    People love comic shows, food-based fun, and light-hearted content, therefore Laughter Chefs – Unlimited Entertainment has become a hot topic. People who want funny and stress-free entertainment search for this keyword.


    What is the Business of Red Chillies Entertainment?

    A well-known Indian entertainment company is Red Chillies Entertainment. People know it for:

    • making movies
    • visual effects (VFX)
    • digital content
    • creative entertainment projects

    Bollywood knows Red Chillies Entertainment for the high quality of its work.


    What Makes Red Chillies Entertainment So Popular

    People like Red Chillies Entertainment because it combines storytelling with technology. Many production houses only focus on films, but Red Chillies Entertainment is known for both movie production and advanced VFX.

    Main Reasons for Popularity

    • strong film production
    • high-level VFX work
    • big Bollywood movies
    • use of modern technology
    • strong branding in the entertainment industry

    In Indian cinema, Red Chillies Entertainment is a major name.


    The VFX Industry and Red Chillies Entertainment

    The VFX department at Red Chillies Entertainment is one of the strongest in the industry. VFX is very important in 2026 because people expect:

    • realistic visuals
    • action-heavy scenes
    • cinematic quality
    • innovative storytelling

    Red Chillies Entertainment helped make Bollywood VFX more advanced and professional.


    Digital Growth and Red Chillies Entertainment

    Movies are not the only type of entertainment in 2026. Red Chillies Entertainment also keeps up with the growth of digital entertainment.

    Digital Entertainment Includes

    • OTT content
    • web series
    • short videos
    • social media content

    Red Chillies Entertainment is part of the new entertainment culture that mixes cinema and digital media.


    What Does NOV Digital Entertainment Do?

    Digital media is growing fast, and NOV Digital Entertainment is part of this digital revolution. Digital entertainment is the future, and companies like NOV Digital Entertainment show how quickly the industry is changing.

    People search for NOV Digital Entertainment because:

    • digital entertainment is increasing
    • people want content online
    • digital creators are growing
    • streaming and short-video platforms are booming

    NOV Digital Entertainment represents a new era of entertainment.


    The Reasons for NOV Digital Entertainment’s Growth

    People now want entertainment that is:

    • fast
    • mobile-friendly
    • easy to access
    • available anytime
    • personalized for viewers

    NOV Digital Entertainment is an example of this digital-first entertainment strategy.


    The Culture of NOV Digital Entertainment and Online Content

    Online entertainment is now a major part of daily life. NOV Digital Entertainment is connected with:

    • online shows
    • digital production
    • social media content
    • influencer collaborations
    • brand entertainment ads

    NOV Digital Entertainment fits perfectly in today’s entertainment industry.


    What is Laughter Chefs – Unlimited Entertainment?

    Laughter Chefs – Unlimited Entertainment is a trending keyword because it combines:

    • comedy
    • fun challenges
    • cooking theme
    • celebrity entertainment
    • light-hearted reality fun

    People love shows that make them laugh, which is why Laughter Chefs – Unlimited Entertainment is trending.


    Why Laughter Chefs – Unlimited Entertainment is Popular Right Now

    It is easy to understand why Laughter Chefs – Unlimited Entertainment is popular in 2026. People are stressed and want fun content.

    People like comedy-based entertainment because:

    • it helps them relax
    • it feels family-friendly
    • it is easy to watch
    • it becomes viral quickly

    Laughter Chefs – Unlimited Entertainment gives people exactly this type of fun.


    Laughter Chefs – Unlimited Entertainment and Reality TV

    Reality TV has changed. Earlier, drama was the main focus. Now audiences want:

    That is why people are paying attention to Laughter Chefs – Unlimited Entertainment.


    Red Chillies Entertainment vs. NOV Digital Entertainment

    Both are entertainment-related, but they belong to different sides of the industry.

    Red Chillies Entertainment

    • film production
    • Bollywood-level projects
    • high-quality VFX
    • movies and premium content

    NOV Digital Entertainment

    • digital-first entertainment
    • internet-based content
    • modern formats
    • growth through social media

    Red Chillies Entertainment is more like classic cinema, while NOV Digital Entertainment is more like modern digital entertainment.


    Why Comedy is the Best Entertainment in 2026

    Comedy is one of the most popular entertainment styles. In 2026, comedy is growing even more because of:

    • reels and short videos
    • meme culture
    • growth of stand-up comedy
    • demand for family-friendly shows

    That is why Laughter Chefs – Unlimited Entertainment matches the current entertainment trend.


    The Entertainment Business in 2026

    The entertainment world is changing rapidly. Entertainment in 2026 includes:

    • cinema
    • OTT web series
    • YouTube channels
    • Instagram reels and comedy shows
    • digital creators
    • VFX-heavy films

    Red Chillies Entertainment leads in cinema and VFX. NOV Digital Entertainment grows through online platforms. Laughter Chefs – Unlimited Entertainment gives people comedy and reality-based fun.


    Why People Search These Entertainment Keywords Together

    People search Red Chillies Entertainment, NOV Digital Entertainment, and Laughter Chefs – Unlimited Entertainment together because:

    • entertainment trends are rising
    • digital content is growing fast
    • comedy shows go viral
    • Bollywood brands still have power

    These keywords represent different types of entertainment in 2026.


    Final Thoughts

    Entertainment is everywhere in 2026. People search Red Chillies Entertainment because it is a big name in Bollywood production and VFX. People search NOV Digital Entertainment because digital entertainment is the future and online content is growing quickly. People search Laughter Chefs – Unlimited Entertainment because comedy and cooking-based reality shows are becoming popular and stress-free.

    All three keywords show how entertainment has evolved. In 2026, entertainment is bigger, faster, and more diverse than ever, including cinema, digital platforms, and comedy reality shows.

  • Έλεγχος αξιοπιστίας λογισμικού MAGICQA20261121NC 00150


    Ο έλεγχος αξιοπιστίας λογισμικού εξετάζει κατά πόσο μια εφαρμογή λειτουργεί σταθερά, προβλέψιμα και με ασφάλεια υπό διαφορετικές συνθήκες. Το MAGICQA20261121NC είναι προσωρινή ετικέτα δημοσίευσης για το παρόν τεχνικό κείμενο και όχι πιστοποίηση ή αποτέλεσμα δοκιμών. Η αξιολόγηση βασίζεται σε σαφώς καθορισμένα κριτήρια, επαναλήψιμες διαδικασίες και τεκμηριωμένα ευρήματα, ενώ η quality assurance 00150 συμβάλλει στη συστηματική επαλήθευση της ποιότητας λογισμικού σε κάθε στάδιο ανάπτυξης. Με αυτόν τον τρόπο, οι ομάδες ανάπτυξης μπορούν να εντοπίζουν αστοχίες, να εκτιμούν τον κίνδυνο και να αποφασίζουν αν μια έκδοση είναι αρκετά ώριμη για διάθεση.

    Τι πρέπει να αξιολογείται στον έλεγχο αξιοπιστίας λογισμικού MAGICQA20261121NC

    Η αξιοπιστία δεν σημαίνει απλώς ότι ένα πρόγραμμα ξεκινά χωρίς μήνυμα σφάλματος. Περιλαμβάνει τη συνέπεια της συμπεριφοράς του, τη διατήρηση των δεδομένων, την αντοχή σε διακοπές και την ικανότητα ανάκαμψης όταν προκύψει πρόβλημα. Για μια ολοκληρωμένη εκτίμηση, η ομάδα ποιότητας ορίζει πρώτα τις κρίσιμες λειτουργίες και τις αναμενόμενες αποκρίσεις τους. Έπειτα εξετάζει τόσο τις συνηθισμένες ροές όσο και τις εξαιρετικές περιπτώσεις, όπως ελλιπή δεδομένα, αργή δικτυακή σύνδεση ή επανεκκίνηση υπηρεσίας. Η ετικέτα MAGICQA20261121NC βοηθά στην αναφορά του συγκεκριμένου συνόλου εργασιών, χωρίς να υποκαθιστά τα ευρήματα ή τα αποδεικτικά στοιχεία.

    Ένας χρήσιμος έλεγχος συνδέει κάθε απαίτηση με μία ή περισσότερες δοκιμές, καθορισμένα δεδομένα εισόδου και μετρήσιμο αποτέλεσμα. Εξετάζονται δείκτες όπως η συχνότητα σφαλμάτων, ο χρόνος απόκρισης, η διάρκεια λειτουργίας και η επιτυχία ανάκαμψης. Η αξιολόγηση πρέπει να γίνεται σε περιβάλλον που προσεγγίζει τη χρήση στην πράξη, αλλά να παραμένει ελεγχόμενο και επαναλήψιμο. Αν αλλάζουν τα δεδομένα, οι ρυθμίσεις ή η έκδοση του λογισμικού, οι αλλαγές καταγράφονται, ώστε τα αποτελέσματα να μπορούν να ερμηνευτούν σωστά και να συγκριθούν με προηγούμενες δοκιμές.

    Πώς οργανώνεται μια επαναλήψιμη διαδικασία ελέγχου

    Η διαδικασία αρχίζει με τον καθορισμό του πεδίου: ποιες λειτουργίες ελέγχονται, ποιες εξαρτήσεις συμμετέχουν και ποια επίπεδα κινδύνου θεωρούνται αποδεκτά. Ακολουθεί η προετοιμασία περιβάλλοντος, δεδομένων και κριτηρίων επιτυχίας. Η εκτέλεση χρειάζεται συνεπή καταγραφή, όχι μόνο των αποτυχιών αλλά και των συνθηκών που προηγήθηκαν. Τα παρακάτω βήματα δημιουργούν ένα πρακτικό πλαίσιο, το οποίο μπορεί να προσαρμοστεί στην αρχιτεκτονική και στις απαιτήσεις κάθε εφαρμογής.

    1. Ορισμός στόχων: Καταγράψτε τις κρίσιμες λειτουργίες, τις απαιτήσεις αξιοπιστίας και τους κινδύνους που πρέπει να καλυφθούν.
    2. Προετοιμασία περιβάλλοντος: Σταθεροποιήστε τις εκδόσεις, τις ρυθμίσεις, τις εξαρτήσεις και τα δεδομένα δοκιμών.
    3. Επιλογή σεναρίων: Συνδυάστε κανονική χρήση με σφάλματα εισόδου, φόρτο, διακοπές και επανεκκινήσεις.
    4. Εκτέλεση και καταγραφή: Αποθηκεύστε αποτελέσματα, χρονικές σημάνσεις, αρχεία καταγραφής και συνθήκες αναπαραγωγής.
    5. Ανάλυση και επανέλεγχος: Ιεραρχήστε τα ευρήματα, διορθώστε τις αιτίες και επαναλάβετε τις σχετικές δοκιμές.
    • Κοινά κριτήρια επιτυχίας μειώνουν τις διαφορετικές ερμηνείες των αποτελεσμάτων.
    • Καταγεγραμμένες ρυθμίσεις διευκολύνουν την αναπαραγωγή μιας αστοχίας.
    • Η επανάληψη μετά τη διόρθωση ελέγχει ότι δεν δημιουργήθηκαν νέες παρενέργειες.
    • Η ταξινόμηση κατά κίνδυνο βοηθά στην ορθή σειρά αντιμετώπισης.

    Πρακτικές δοκιμές αξιοπιστίας για το MAGICQA20261121NC

    Στο πρακτικό μέρος, η ετικέτα MAGICQA20261121NC μπορεί να χρησιμοποιηθεί ως αναγνωριστικό μιας παρτίδας δοκιμών, ώστε τα σχετικά αρχεία και οι αναφορές να εντοπίζονται εύκολα. Το σύνολο ελέγχων μπορεί να περιλαμβάνει δοκιμές αντοχής, όπου η εφαρμογή λειτουργεί για παρατεταμένο διάστημα, καθώς και δοκιμές φόρτου, όπου αυξάνεται σταδιακά ο αριθμός αιτημάτων. Χρειάζονται επίσης σενάρια αστοχίας εξαρτήσεων, όπως προσωρινή απώλεια σύνδεσης με υπηρεσία ή καθυστέρηση απόκρισης. Σε κάθε περίπτωση, το ζητούμενο δεν είναι μόνο αν η εφαρμογή αποτυγχάνει, αλλά αν το κάνει με ελεγχόμενο τρόπο και αν επανέρχεται χωρίς απώλεια ή αλλοίωση δεδομένων.

    Οι δοκιμές πρέπει να λαμβάνουν υπόψη τη διαφορά ανάμεσα σε ένα μεμονωμένο περιστατικό και σε επαναλαμβανόμενη τάση. Για παράδειγμα, μια μικρή αύξηση χρόνου απόκρισης μπορεί να είναι αποδεκτή σε χαμηλό φόρτο, αλλά αν επιδεινώνεται όσο περνά ο χρόνος, ενδέχεται να υποδηλώνει διαρροή πόρων. Η παρακολούθηση χρήσης μνήμης, επεξεργαστικής ισχύος, αποθηκευτικού χώρου και ουρών αιτημάτων προσφέρει στοιχεία για τέτοιες συμπεριφορές. Τα αποτελέσματα συνοδεύονται από σαφή περιγραφή του περιβάλλοντος, ώστε να μην αποδίδεται λανθασμένα στην εφαρμογή ένα πρόβλημα που οφείλεται σε εξωτερικό παράγοντα.

    • Δοκιμή διάρκειας: Ελέγχει αν η λειτουργία παραμένει σταθερή σε παρατεταμένη χρήση.
    • Δοκιμή φόρτου: Μετρά την απόκριση καθώς αυξάνεται ο αριθμός ταυτόχρονων αιτημάτων.
    • Δοκιμή ανάκαμψης: Επιβεβαιώνει την ασφαλή επαναφορά μετά από διακοπή ή επανεκκίνηση.
    • Έλεγχος δεδομένων: Εξετάζει αν οι εγγραφές παραμένουν πλήρεις και συνεπείς μετά από αστοχία.

    Η χρησιμότητα αυτών των ελέγχων εξαρτάται από την ποιότητα των μετρήσεων και από το αν τα σενάρια αντιστοιχούν σε πραγματικούς κινδύνους. Μια επιτυχής δοκιμή δεν αποδεικνύει ότι δεν υπάρχουν σφάλματα· δείχνει μόνο ότι η εφαρμογή ικανοποίησε συγκεκριμένα κριτήρια υπό συγκεκριμένες συνθήκες. Για τον λόγο αυτό, η αναφορά πρέπει να αναφέρει περιορισμούς, γνωστά κενά κάλυψης και παραδοχές. Έτσι, οι υπεύθυνοι μπορούν να κατανοήσουν τι ελέγχθηκε και τι παραμένει προς διερεύνηση.

    Οφέλη από τη συστηματική διασφάλιση αξιοπιστίας

    Η οργανωμένη διασφάλιση ποιότητας κάνει τις αποφάσεις για μια έκδοση πιο τεκμηριωμένες. Αντί να βασίζονται σε γενική εντύπωση, οι ομάδες εξετάζουν επαναλήψιμα αποτελέσματα και τάσεις σε βάθος χρόνου. Η έγκαιρη ανίχνευση προβλημάτων μειώνει την πιθανότητα να φτάσουν σοβαρές αστοχίες στους χρήστες και περιορίζει το κόστος αποκατάστασης. Παράλληλα, οι κοινές διαδικασίες διευκολύνουν τη συνεργασία μεταξύ ανάπτυξης, λειτουργίας και ελέγχου ποιότητας. Τα οφέλη είναι πιο ουσιαστικά όταν οι δοκιμές ενσωματώνονται στον κύκλο ανάπτυξης και όταν κάθε εύρημα οδηγεί σε σαφή ενέργεια, υπεύθυνο και επανέλεγχο.

    • Έγκαιρος εντοπισμός: Αποκαλύπτονται αστοχίες πριν επηρεάσουν ευρύτερη λειτουργία.
    • Καλύτερη ιχνηλασιμότητα: Κάθε αποτέλεσμα συνδέεται με απαίτηση, έκδοση και περιβάλλον.
    • Σταθερότερες εκδόσεις: Οι επαναληπτικοί έλεγχοι εντοπίζουν ανεπιθύμητες παλινδρομήσεις.
    • Σαφέστερη προτεραιοποίηση: Η σοβαρότητα και η πιθανότητα εμφάνισης καθοδηγούν τις διορθώσεις.

    Η ετικέτα MAGICQA20261121NC μπορεί να εμφανίζεται στα ονόματα αναφορών και στα αρχεία δοκιμών για σκοπούς οργάνωσης. Η χρήση της πρέπει να παραμένει περιγραφική: δεν αποτελεί από μόνη της ένδειξη συμμόρφωσης, πιστοποίησης ή εγγύησης αξιοπιστίας. Η διάκριση αυτή προστατεύει την ακρίβεια της τεχνικής επικοινωνίας και αποτρέπει την υπερερμηνεία ενός επιτυχημένου αποτελέσματος.

    Ασφάλεια, ακεραιότητα δεδομένων και τεκμηρίωση ευρημάτων

    Ο έλεγχος αξιοπιστίας συνδέεται στενά με την ασφάλεια, επειδή μια αστοχία μπορεί να επηρεάσει τη διαθεσιμότητα, την ακεραιότητα ή την εμπιστευτικότητα των δεδομένων. Τα περιβάλλοντα δοκιμών πρέπει να χρησιμοποιούν κατάλληλα δικαιώματα πρόσβασης και να αποφεύγουν την έκθεση πραγματικών ευαίσθητων πληροφοριών. Οι διαδικασίες ανάκαμψης χρειάζεται να επιβεβαιώνουν όχι μόνο ότι η υπηρεσία ξεκινά ξανά, αλλά και ότι οι εγγραφές παραμένουν ορθές και ότι δεν δημιουργούνται διπλές ή ελλιπείς συναλλαγές δεδομένων. Επιπλέον, τα αρχεία καταγραφής πρέπει να συλλέγονται με τρόπο που υποστηρίζει τη διερεύνηση, χωρίς να αποθηκεύει περιττές ευαίσθητες τιμές.

    Μια τεχνική αναφορά πρέπει να περιγράφει το αναμενόμενο και το πραγματικό αποτέλεσμα, τα βήματα αναπαραγωγής, τη σοβαρότητα και την έκταση του αντίκτυπου. Χρήσιμα είναι επίσης τα στοιχεία περιβάλλοντος, όπως η έκδοση, οι βασικές ρυθμίσεις και οι εξαρτήσεις που συμμετείχαν. Η καταγραφή ενός προβλήματος πρέπει να διαχωρίζει την παρατήρηση από την υπόθεση για την αιτία, ώστε η διερεύνηση να παραμένει αντικειμενική. Μετά τη διόρθωση, ο επανέλεγχος επιβεβαιώνει την επίλυση και εξετάζει γειτονικές λειτουργίες για πιθανές παρενέργειες. Αυτή η πρακτική δημιουργεί αξιόπιστο ιστορικό ποιότητας και υποστηρίζει υπεύθυνες αποφάσεις διάθεσης.

    Κριτήρια αξιολόγησης για το MAGICQA20261121NC

    Η αξιολόγηση ενός συνόλου ελέγχων με την προσωρινή ετικέτα MAGICQA20261121NC πρέπει να βασίζεται στην κάλυψη, στην επαναληψιμότητα και στη σαφήνεια των ευρημάτων. Πριν από την ολοκλήρωση, επιβεβαιώστε ότι οι κρίσιμες απαιτήσεις έχουν αντιστοιχιστεί σε δοκιμές, ότι τα αποτυχημένα σενάρια μπορούν να αναπαραχθούν και ότι οι περιορισμοί έχουν καταγραφεί. Εξετάστε επίσης αν τα όρια αποδοχής έχουν οριστεί εκ των προτέρων, αντί να επιλέγονται μετά την εμφάνιση των αποτελεσμάτων. Έτσι αποφεύγονται αυθαίρετα συμπεράσματα και διατηρείται κοινή βάση αξιολόγησης για τις επόμενες εκδόσεις του λογισμικού.

    Για να κριθεί αν η διαδικασία είναι επαρκής, εξετάστε πόσο γρήγορα εντοπίζονται οι αστοχίες, πόσο αξιόπιστα αναπαράγονται και αν η ανάκαμψη διατηρεί την ορθότητα των δεδομένων. Η απόφαση δεν χρειάζεται να είναι απόλυτη: μπορεί να καταγράφει αποδεκτούς κινδύνους, εκκρεμείς διορθώσεις και πρόσθετους ελέγχους που απαιτούνται. Το σημαντικό είναι κάθε συμπέρασμα να στηρίζεται σε συγκεκριμένα τεκμήρια και να παραμένει σαφές ότι οι δοκιμές καλύπτουν ορισμένες συνθήκες, όχι κάθε πιθανή χρήση. Με τέτοια προσέγγιση, ο έλεγχος αξιοπιστίας γίνεται πρακτικό εργαλείο συνεχούς βελτίωσης και όχι απλή τυπική επιβεβαίωση.

  • Software reliability check MAGICQA20261111AI 01939


    Software quality assurance helps teams determine whether an application performs consistently, protects its data, and behaves as expected under real operating conditions, with quality assurance 01939 reflecting the broader discipline of testing software against clear standards. This article uses MAGICQA20261111AI as a temporary publication test label, not as a product endorsement or a claim of certification. It explains how to plan reliability checks, gather useful evidence, interpret failures, and decide what to improve. A structured approach makes quality decisions more repeatable and helps teams connect test results to user impact, operational risk, and release readiness.

    The basics that shape smart software quality assurance decisions

    Software reliability describes the likelihood that a system will continue to operate correctly over a defined period and under specified conditions. Quality assurance supports that goal through planned activities across development, testing, deployment, and maintenance. A reliability check is therefore more than a single test run: it combines clear expectations, representative workloads, failure observations, and evidence that can be reviewed. Teams should distinguish reliability from related qualities such as usability, performance, and security while recognizing that failures can cross these boundaries. For example, a slow dependency may cause timeouts, which can appear to users as an unavailable feature.

    Useful checks begin with measurable expectations. A team might define acceptable service availability, recovery time, error rates, data consistency, or successful completion rates for important workflows. Those expectations should reflect the system’s intended use and the consequences of failure, rather than being selected only because they are easy to measure. The MAGICQA20261111AI label can identify this temporary publication test, while test plans and reports should still record the application build, environment, configuration, date, and observed results. Clear records allow reviewers to reproduce findings and compare reliability over time without confusing test labels with technical evidence.

    How to establish a software reliability check

    A practical reliability process moves from risk definition to repeatable evidence. Before execution, identify the functions that matter most, the conditions that could disrupt them, and the signals that would reveal a problem. Then choose checks that match those risks: repeated workflow tests, load and soak testing, recovery exercises, or controlled fault injection. The sequence below provides a starting framework, but teams should adjust its depth to system architecture, release scope, and user impact.

    1. Set reliability objectives: Define observable targets for availability, error rates, recovery, and data integrity for critical workflows.
    2. Map failure risks: Identify dependencies, resource limits, state changes, and operating conditions that could interrupt expected behavior.
    3. Prepare a representative environment: Record the build, configuration, data assumptions, and dependency versions so results can be interpreted and repeated.
    4. Run targeted checks: Combine functional repetition with suitable load, endurance, recovery, and fault scenarios rather than relying on one test type.
    5. Review evidence and act: Connect logs, metrics, traces, and user-visible outcomes to each finding, then assign corrective work and retest.
    • Defined objectives make pass and fail decisions less subjective.
    • Risk mapping focuses effort on consequential failure modes.
    • Recorded environments improve reproducibility across test runs.
    • Retesting confirms whether corrective changes address the original issue.

    Practical reliability checks for software systems

    Reliability testing is most informative when it reflects how software is actually used. For a service with several connected components, test critical journeys from entry point to final result and observe both the overall outcome and intermediate dependencies. Repeating those journeys can expose intermittent faults that a one-time functional test misses. Load tests help assess behavior as demand increases, while soak tests can reveal resource leaks or degradation during sustained activity. Recovery checks should examine what happens after a process restart, network interruption, or dependency outage, including whether the system restores a valid state without duplicating or losing important data.

    Test data and system conditions need careful control. Use representative, non-sensitive data and document any assumptions about data volume, user concurrency, and dependency availability. Instrumentation should capture enough context to explain what happened without collecting unnecessary personal information. For each scenario, define the expected result, duration, workload, and failure threshold before execution. The following evidence can help make a reliability report useful to developers and operational reviewers:

    • Workflow outcomes: Record successful, failed, timed-out, and incomplete critical transactions.
    • Service indicators: Track latency percentiles, error rates, resource use, and availability against agreed thresholds.
    • Diagnostic context: Preserve relevant logs, traces, timestamps, and component versions for investigation.
    • Recovery observations: Note detection time, restoration time, data state, and any manual intervention required.

    Results should be interpreted in context rather than reduced to a single pass label. A low average error rate can conceal a severe failure in one important workflow, while a brief test may not expose degradation that appears after hours of sustained use. Review trends alongside release changes, environment differences, and known limitations. When a check fails, record the conditions that triggered it, whether the behavior is repeatable, and the scope of impact. This creates a practical bridge between test evidence and prioritized engineering work, while keeping reliability decisions grounded in observable behavior.

    Key benefits of a disciplined quality assurance process

    Consistent reliability checks help teams find weaknesses before they become widespread operational incidents. Their value comes not only from detecting defects but also from making system behavior more understandable. A team that records objectives, scenarios, and outcomes can compare releases, identify recurring patterns, and assess whether a change improved the intended measure without creating a new problem elsewhere. Checks also support clearer discussions between developers, testers, product owners, and operations staff because findings can be linked to expected behavior and user impact. Benefits depend on suitable coverage and honest reporting; test activity alone does not guarantee reliability.

    • Earlier defect discovery: Repeated and risk-focused checks can reveal intermittent faults before release.
    • More informed release decisions: Measured thresholds provide evidence for accepting, delaying, or limiting a deployment.
    • Faster diagnosis: Correlated logs and metrics help teams narrow the cause of a failure.
    • Better recovery readiness: Exercises expose gaps in restoration procedures and state handling.
    • Useful trend analysis: Comparable records show whether reliability is improving or deteriorating over time.

    These benefits are strongest when quality assurance is integrated throughout the software life cycle. Early design reviews can identify fragile dependencies, automated checks can run repeatedly during development, and operational monitoring can reveal behavior that laboratory tests did not reproduce. Teams should also revisit scenarios when architecture, usage patterns, or risk assumptions change. A check that once represented real conditions may become misleading after a major change. Maintaining test intent alongside test results helps prevent outdated checks from creating false confidence and keeps quality assurance relevant as the software evolves.

    Trust, security, and reliable test evidence

    Reliable quality assurance depends on trustworthy evidence and controlled test practices. Test environments should be separated from production unless a carefully authorized production exercise has been designed with safeguards. Access to test systems and datasets should follow least-privilege principles, and sensitive information should be masked or replaced with suitable synthetic data. Reports should state what was tested, what was excluded, and what limitations could affect interpretation. This transparency helps decision-makers avoid treating a narrow test as proof that every operating condition is safe. The temporary label MAGICQA20261111AI is only an identifier for this publication test and should not be presented as evidence of a product, audit, or formal approval.

    Security and reliability are connected because attacks, configuration errors, and weak access controls can interrupt service or corrupt data. However, reliability testing does not replace security assessment, privacy review, or operational readiness work. Teams should coordinate these activities where their scope overlaps, such as validating safe failure behavior or checking that recovery processes preserve access controls. Findings should be assigned owners, impact levels, and review dates, with sensitive diagnostic details shared only with authorized staff. A documented retest can confirm that a fix works under the original conditions and that related workflows remain stable, supporting responsible release decisions without overstating what the evidence proves.

    Why choose a measured approach to software reliability

    A measured approach is useful when an organization needs repeatable answers about whether software behaves dependably under defined conditions. The right choice is not a particular test label or a large number of test cases; it is a process that connects realistic scenarios to clear objectives and records evidence that others can inspect. Before approving a release, reviewers can ask whether critical workflows were covered, whether representative load and recovery conditions were considered, whether failures have owners, and whether unresolved risks are understood. They should also confirm that test environments and data were handled appropriately and that the report describes important limitations.

    MAGICQA20261111AI remains a temporary publication test label, while software reliability depends on the quality of the checks and the decisions made from their results. Teams can begin with a small set of high-impact workflows, establish measurable thresholds, and expand coverage as evidence identifies new risks. Repeating checks after meaningful changes makes comparisons more useful and helps expose regressions. By combining planned tests, clear instrumentation, responsible data practices, and documented follow-up, software quality assurance can provide a practical basis for improving reliability without claiming certainty beyond what the tests demonstrate.

  • Software reliability check MAGICQA20261111AK 01140


    Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers safely when failures occur. This technical overview uses the temporary publication test label MAGICQA20261111AK to identify the content, not a product or quality certification. It explains how software quality assurance, including quality assurance 01140 , supports planning reliability tests, gathering useful evidence, and interpreting results across releases. The emphasis is on repeatable methods that connect observed behavior to user impact, operational risk, and measurable acceptance criteria.

    What to assess before planning software reliability checks

    Reliability is the ability of software to perform required functions consistently over time, within defined operating conditions. A useful check therefore begins with the system’s intended behavior, not merely with a list of test tools. Teams should identify critical workflows, dependencies, supported environments, and the consequences of interruption or incorrect results. They can then define measurable expectations, such as successful transaction completion, acceptable response time, data integrity, and recovery objectives. Clear boundaries make test results easier to interpret: a service may be reliable under ordinary traffic yet fail when a dependency slows down or a workload lasts for several hours.

    Software quality assurance combines preventive practices with verification. Code review, static analysis, component tests, integration tests, and operational monitoring each reveal different kinds of risk. Reliability checks bring these signals together by asking whether the whole system continues to meet its requirements as conditions change. The temporary label MAGICQA20261111AK can be included in test documentation or publication records to identify this evaluation context. It should not be treated as evidence of a passed test. Confidence comes from traceable requirements, representative test conditions, repeatable execution, and documented findings.

    How to run a step-by-step reliability assessment

    A structured assessment reduces the chance that teams will mistake a successful test run for proof of dependable behavior. Before execution, agree on the build, environment, test data, duration, and pass or fail thresholds. Keep a record of deviations, because a test performed with missing dependencies or unrepresentative data may not support a meaningful release decision. The following sequence creates a practical baseline while allowing teams to adapt the depth of testing to the software’s risk and service objectives.

    1. Define critical requirements: Identify essential user journeys, data rules, service-level targets, and recovery expectations.
    2. Map dependencies and risks: Record external services, databases, queues, infrastructure components, and likely failure points.
    3. Prepare a representative environment: Match relevant production settings, workload patterns, access controls, and test data characteristics.
    4. Exercise normal and stressed conditions: Run functional, load, endurance, and controlled failure tests against agreed thresholds.
    5. Analyze evidence and retest: Investigate failures, document their impact, verify fixes, and compare results with the baseline.
    • Written thresholds help distinguish acceptable variation from a reliability defect.
    • Dependency mapping directs attention toward failures that can affect complete workflows.
    • Controlled test conditions make comparisons between builds more meaningful.
    • Retesting confirms whether corrective changes resolve the underlying problem.

    Practical reliability checks for software quality assurance

    Practical checks should reflect how the application is used and how it can fail. Functional tests verify that important operations produce correct outcomes, while integration tests examine exchanges between components. Load tests measure behavior as concurrent demand increases; stress tests explore the point at which performance or correctness deteriorates. Endurance tests can reveal resource leaks, gradual latency increases, or unstable background processing. Recovery tests examine whether the system resumes service after a process restart, network interruption, or dependency outage. For each method, define a controlled scenario and capture evidence such as error rates, latency percentiles, resource use, logs, and data consistency.

    • Data integrity: Confirm that retries, interruptions, and repeated requests do not create lost or duplicated records.
    • Service continuity: Track successful operations and error rates during realistic workload changes.
    • Recovery behavior: Measure restoration time and verify that essential functions resume correctly.
    • Resource stability: Observe memory, processor use, connection pools, and queue depth during extended runs.
    • Diagnostic quality: Check that logs and alerts help engineers identify the affected component and failure period.

    For the publication test identified by MAGICQA20261111AK, teams can use the label in a test plan, report, or build record to connect related evidence. The label itself does not determine whether the software is dependable; the test scope and results do. Reports should note the software version, environment configuration, test duration, workload profile, and known limitations. If a test fails, capture reproducible steps and supporting telemetry before changing the environment. This practical discipline supports root-cause analysis and prevents teams from closing a reliability issue simply because a later run happened to pass.

    Key benefits of consistent reliability testing

    Regular reliability checks give quality assurance teams a clearer view of how software behaves beyond a single successful transaction. When the same scenarios and measures are applied across builds, trends can expose gradual degradation before it becomes a user-facing incident. Findings also make engineering discussions more concrete: teams can prioritize defects by their impact on critical workflows, the likelihood of recurrence, and the quality of available workarounds. Benefits depend on sound test design and responsible interpretation. A test suite cannot guarantee that every failure has been discovered, but it can improve the evidence available for release and operational decisions.

    • Earlier risk discovery: Controlled failure and endurance scenarios can reveal weaknesses before deployment.
    • More informed releases: Measured results support decisions against explicit reliability objectives.
    • Improved diagnosis: Linked test records, logs, and metrics shorten the path from symptom to investigation.
    • Stronger regression coverage: Repeatable checks help detect when changes affect previously stable behavior.

    These benefits are strongest when reliability checks are integrated into the quality process rather than reserved for a final gate. Fast automated checks can run frequently, while longer endurance and recovery scenarios can run on a planned schedule or before higher-risk releases. Teams should review failures and flaky tests routinely, since unstable test infrastructure can obscure real defects. A concise report that explains coverage, evidence, exceptions, and unresolved risks is more useful than a pass label without context. The goal is actionable understanding, not a claim that the software is free of all defects.

    Trust, security, and dependable test evidence

    Reliable software must also protect data and control access appropriately. Quality assurance checks should verify that authentication and authorization rules remain effective during normal use, error handling, and recovery. Test data should be synthetic or carefully governed so that sensitive information is not exposed in logs, reports, or shared environments. Teams should also confirm that backups and restoration procedures preserve required data and that recovery does not bypass security controls. These checks complement performance and availability testing: a system that remains online but returns incorrect information or exposes restricted records has not met its reliability expectations.

    Trustworthy conclusions depend on evidence that can be reviewed and reproduced. Preserve the test configuration, software build identifier, workload definition, relevant logs, and outcome measurements. Record both successful results and limitations, including untested dependencies, environment differences, and any manual steps. Use access controls and retention rules for test artifacts, particularly where operational details could be sensitive. The publication label MAGICQA20261111AK can help distinguish this content or its associated records, but it does not replace independent review, security assessment, or formal acceptance criteria. Such transparency prevents a temporary test reference from being mistaken for a guarantee or certification.

    Why use MAGICQA20261111AK in a reliability review

    Use MAGICQA20261111AK as a clear temporary reference when organizing material about software reliability checks. A useful review should still be judged by its scope, repeatability, evidence quality, and connection to defined requirements. Before relying on results, confirm that critical workflows were covered, test conditions were appropriate, thresholds were set in advance, and defects were tracked through verification. Consider whether the review examined data integrity, load behavior, recovery, and security as relevant to the system. This decision-focused approach keeps attention on software quality assurance rather than on the label attached to a publication or test record.

    A dependable process is iterative: establish a baseline, test realistic operating conditions, investigate deviations, correct root causes, and repeat the checks. Share results with developers, quality specialists, and operations staff so that reliability risks are understood across the teams responsible for the software. Keep unresolved risks visible and state what the evidence does not cover. With those practices, a reliability review becomes a practical input to engineering decisions and continuous improvement. The temporary label provides traceability for this article, while carefully planned tests and transparent findings provide the substance needed to assess software behavior.

  • Example Post for WordPress

    This is a sample post created to test the basic formatting features of the WordPress CMS.

    Subheading Level 2

    You can use bold text, italic text, and combine both styles.

    1. Step one
    2. Step two
    3. Step three

    This content is only for demonstration purposes. Feel free to edit or delete it.

  • Crypto AI trading bots: A beginner’s guide

    AI-powered trading automation

    The platform includes real-time Data Scanner tools, Signal Scanner event detection, News Scanner functionality, QuickView research panels, custom alerts, and more than 65 real-time filters across price, volume, change, technicals, fundamentals, and market activity. This makes it useful for traders who already have a strategy or alert workflow and want to automate order placement across stocks, ETFs, options, futures, and crypto without building custom broker integrations. TradersPost is an automated trading platform that allows users to turn alerts, signals, and strategy conditions into live orders across connected broker accounts. Tickeron’s broader toolkit includes AI Robots, an AI Pattern Search Engine, AI Trend Prediction Engine, AI Stock Screener, AI Real Time Patterns, Daily Buy/Sell Signals, and educational resources through its Academy. This makes Tickeron especially useful for active traders who want AI-assisted decision support rather than a simple stock screener.

    The best AI stock trading bot in 2026 is Trade Ideas, for its AI-powered scanning, real-time alerts, and automated strategy tools. From Trade Ideas’ adaptive Holly engine to Public.com’s natural-language Agentic Brokerage, the tools available today can genuinely transform how you research, execute, and manage your portfolio. Platforms like Tickeron natural language processing can also automate the buying and selling of crypto assets based on their predictive models. Its proprietary AI engine, “Holly,” runs millions of simulated trades nightly to provide curated, high-probability signals for the following day.

    SignalStack is a no-code trade automation platform that turns alerts from charting tools and trading systems into live orders inside connected brokerage or exchange accounts. Capitalise.ai’s core technology is built around natural language processing, allowing users to move from an idea to a rules-based trading https://aicurated.com/ strategy without writing code. StockHero also supports paper trading with simulated real-time market data, risk controls such as per-bot capital allocation, and an AI chatbot that can help users navigate trading-related questions. TrendSpider also supports broker-connected workflows through integrations and automation tools, allowing traders to move from research to execution with fewer manual steps.

    AI-powered trading automation

    Free AI Trading Tools That Actually Work (2026 Guide)

    Some platforms report higher “win rates”; for example, Danelfin reports a win rate of 60%+, and Tickeron reports win rates of up to 86.6% over certain periods. For maximum reliability, use platforms with transparent, explainable AI like Tickeron or Danelfin that show the logic behind their signals. In 2026, the cost of AI trading software generally ranges from $30 to $100 per month for standard tiers, though professional-grade tools with real-time data can exceed $250 per month. While platforms like TradeStation require mastery of EasyLanguage, StockHero uses a simple visual wizard. StockHero focuses on lowering the cognitive barrier of entry for automated trading through pre-configured bot architectures and white-glove setup options.

    AI-powered trading automation

    • If you’re using the Stock Hero AI trading app, that might mean creating a basic bot through its wizard and browsing the marketplace carefully.
    • They surface insights and alerts, but ultimately rely on the user to make and execute trades.
    • StockHero runs bots that execute your strategy or one you rent from its marketplace.
    • In 2026, agentic coding tools such as Claude Code and Google’s Antigravity have made it easier to build more sophisticated automated trading projects with the right prompts.
    • AI Sidekick All plans; 25 messages/month, with higher limits on upper tiers AI assistant for market research.

    AI trading uses a layered architecture to process datasets and execute decisions faster than human capability. This guide provides a complete framework for evaluating and selecting the right AI trading platform for your needs in 2026. The technology is the same engine institutional desks have used for decades; the 2026 difference is that retail investors now have access through platforms large language models starting at $0/month. Use paper trading where available, verify broker and data-feed compatibility, set independent position and loss limits, and monitor live automation closely. The best fit depends on the markets you trade, the amount of automation you want, your brokerage setup, and how much control you need over strategy design and risk limits.

    • Offers a “Trend Prediction Engine” and a marketplace for AI-managed portfolios.
    • It is built around “AI Robots” that track and manage specific asset portfolios.
    • AI tools can enhance speed and data processing, but they are not a guarantee of profit.
    • Tickeron utilizes “Financial Learning Models” to provide probability-based trade ideas.
    • Features include native ONNX ML model deployment, a massive marketplace for pre-made EAs and deep historical backtesting tools.
    • We have quickly grown into the digital news source for an emerging generation of cryptocurrency enthusiasts, reaching more than a million readers on a monthly basis, across the globe.
    • They run on Public’s real-time price data, and you review every workflow before it goes live, with all activity logged in your account.

    Technical Analysis and Pattern Recognition

    Tickeron is an AI-powered trading intelligence platform Tradeview’s EDGE Puts AI to Work Inside Trade Execution that provides traders with machine learning-driven stock, ETF, and crypto signals, trading robots, screeners, pattern recognition, and price prediction tools. Users can automate single alerts or full strategies, connect multiple broker accounts, trade live or simulated accounts, and define order directions using market, limit, stop, stop-limit, and sell-to-close order types. Rather than generating its own trading signals, research, or investment recommendations, SignalStack is designed as an execution bridge that lets traders automate the strategies and alerts they already use.

    The “best” application is inherently subjective; a non-coding investor seeking guided insights requires a fundamentally different architecture than a technical quant deploying custom Pine Script frameworks. The following comparison matrix evaluates the top platforms across their primary capabilities, assets, pricing, and our Weighted Dimension Score (based on AI sophistication, cost, compliance, and usability). The following checklist is based on best practices recommended by CFTC, along with platform-specific security documentation.

    AI-powered trading automation

    AI-powered trading automation

    Its “Kai Score” is an essential tool for systematic investors who need a quick, data-backed screening process to support their manual execution. While other tools alert you to a pattern AI agents as it happens, “Holly” has already run the simulations to tell you the statistical likelihood of that pattern’s success based on current market conditions. Trade Ideas focuses on real-time AI scanning and success-filtered alerting, powered by its proprietary “Holly” engine. Tickeron maintains its position as a comprehensive suite for pattern recognition and trend prediction.